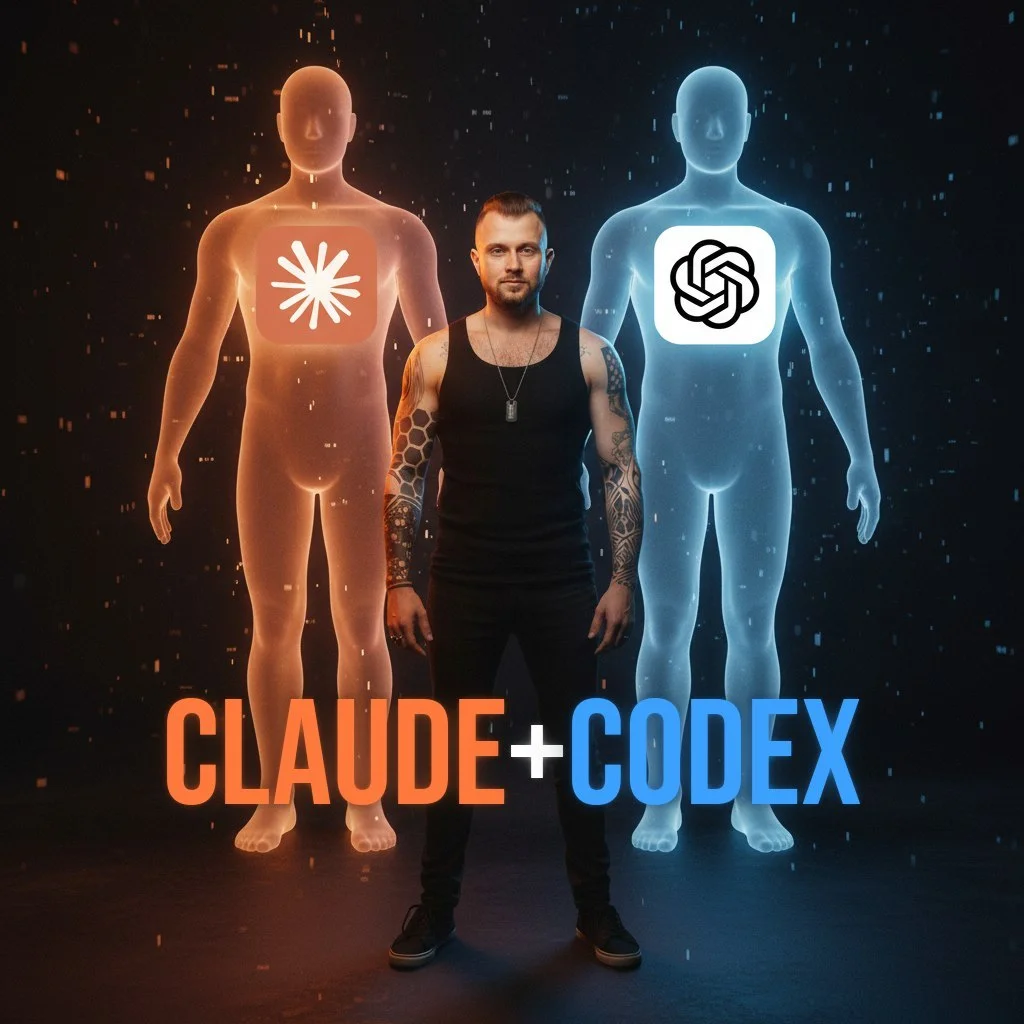
🔥 For three months I trusted my code to one agent and thought that was enough. Put a second one on as a reviewer - it found holes on day one. I pay exactly the same, but the reliability is on a different level
Why one agent is an architectural limitation
Claude Code and Codex are built on different principles. Claude Code is a local agent: it builds up memory about the project between sessions, sees the full file context, works interactively. Codex is a cloud sandbox launched by OpenAI in May 2025: it works asynchronously, connects to GitHub repos, opens PRs with no user involved. The model under the hood is ChatGPT 5.5
How the setup works
✅ Codex on a VPS - a separate 24/7 agent: its own Telegram bot, its own MEMORY.md, its own systemd service, access to vault-search. I send tasks from my phone - it executes them. No API keys, no token billing - just the ChatGPT subscription. It's not an SSH bridge, it's a full-fledged agent: its own project context, its own tasks/, its own conversation history
✅ Claude Code - coordinator and primary writer: diagnoses the VPS, fixes cron, writes scripts, sets up monitoring, keeps the full system context between sessions. This is brain number one
✅ Codex - independent reviewer in VS Code: the same code goes through Codex for a second pass after Claude. Two independent opinions on one file. If both agree - the fix is solid. If they disagree - there's something to dig into
What the setup delivered on 4 projects
📌 The second agent catches the first one's holes - not because the first is bad, but because the architectures are different. Cross-review removes confirmation bias: one model can't honestly check itself
📌 $220/mo with no API billing on top - $200 Claude Max + $20 ChatGPT Plus. Subscriptions I was already paying for anyway. Codex on the VPS runs on the ChatGPT subscription, not on tokens
📌 Parallelism at no extra cost - Claude drives a complex interactive task, Codex keeps a routine one running in the background on the VPS. Different task types, different agents, one codebase
📌 You can't blindly trust just one - that's proven in practice, not in theory. On all 4 projects the second agent sent back for rework what the first one missed
What grew out of it
The setup has grown since then. I now run 8 Claude Code agents every day with different roles, and their brains are Sonnet 5 and Opus 5.5 for different tasks. The second-pair-of-eyes principle stayed: one model does the work, another checks it. My personal agent Jes has a primary model and an automatic backup: if the first fails, the second carries on by itself. Jes has been running for 134 days and since July has handed 165 tasks to other bots
I bring the same approach to clients: AI assistants run for five people on their own servers and their own subscriptions, and a clinic owner runs 6 agents. No token billing on top, just a subscription and a server
How to repeat it
Start with one agent that writes and a second one that only reviews. The second doesn't need write access: let it read the changes and leave comments. If both agree, the change goes ahead; if they disagree, you decide. A pair like this costs two subscriptions and catches what a single model misses in its own work
Key takeaway
From discussions on the OpenAI Community: both agents use the same base models. The winner is the one with the better harness - memory, tasks, context, parallelism. It's the harness that compounds over time, not the model itself. A two-agent setup is a double harness, where each one is optimized for its own type of task
⭐️ Eric Raymond, author of "The Cathedral and the Bazaar": "Given enough eyeballs, all bugs are shallow"
🙃 For three months I got by with one agent and thought it was enough. The second one found holes on day one. Could've done it sooner - but now I know the difference not from an article, but from 4 live projects